Latest update: 2026-08-21
This guide illustrates how to create and integrate an accelerator with the ESP high-level synthesis (HLS) flow, using Keras/PyTorch/ONNX as the specification languages, and hls4ml and Vivado HLS to generate a corresponding RTL implementation.
Platform support: This hls4ml/Vivado HLS flow is currently limited to AMD/Xilinx FPGA targets. It is not supported by the Intel/Altera DE10-Pro SX flow; use the RTL or Third-Party accelerator flow on that board.
External-version notice: the generated-source integration in this guide was written for the hls4ml v0.2-era Vivado HLS flow. Current upstream hls4ml is substantially newer and is not a drop-in replacement for these steps. The checkout below is pinned to the nearest published release instead of cloning a moving branch. This flow still needs end-to-end revalidation with ESP 2026.1.0 and the listed CAD-tool version.
Make sure to complete the prerequisite tutorials before getting started with this one. This tutorial assumes that accelerator designers are familiar with the ESP infrastructure and know how to run basic make targets to create a simple instance of ESP, integrating just a single core.
This guide teaches how to use the Keras/PyTorch/ONNX ESP accelerator design flow, which comprises two main steps:
-
Generate with hls4ml a C/C++ accelerator for Vivado HLS starting from a Keras/PyTorch/ONNX neural network model.
-
Run an ESP interactive script to automatically integrate the accelerator in ESP and generate unit-test applications: a C/C++ testbench, a bare-metal application, and a Linux user-space application.
hls4ml is a very interesting open-source tool, developed by the Fast ML Lab, that takes as input a neural network model specified in Keras TensorFlow, PyTorch or ONNX and automatically generates a hardware accelerator for it. The accelerator is specified in C/C++ and it can be synthesized into RTL automatically with high-level synthesis by Xilinx Vivado HLS. Vivado HLS targets FPGA only, but the ASIC path for hls4ml is in the works. Originally developed for research in particle physics, hls4ml used to target very small and ultra-low latency networks. Now, however, it has broad applicability.
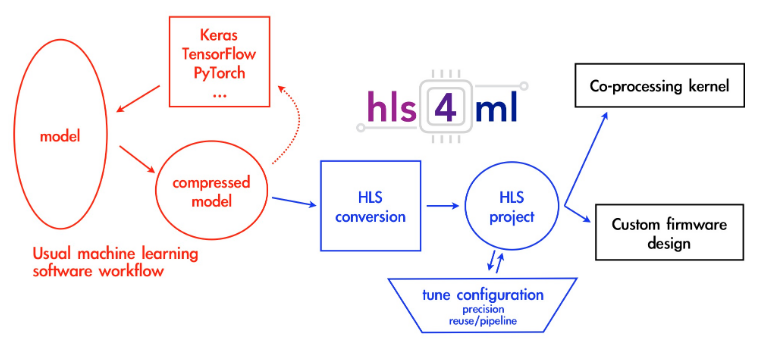
[ Image from https://fastmachinelearning.org/hls4ml/CONCEPTS.html ]
In this guide and in the corresponding prebuilt material we generate and integrate in ESP one of the sample accelerator available in the hls4ml repository: an accelerator that implements multi-layer perceptron (MLP) with 3 layers.
This tutorial is a simple example that will introduce users to the automation mechanisms offered by ESP to integrate accelerators generated with hls4ml. This tutorial, instead, will not explore all the capabilities of the hls4ml tool.
Note: The users have access to prebuilt material to run the tutorial on an FPGA, without executing all the previous steps. See the ‘FPGA prototyping with prebuilt material’ section at the end of this guide.
1. Accelerator generation
Given a neural network model specified in Keras TensorFlow, PyTorch or ONNX, hls4ml can automatically generate an accelerator specified in C/C++ and synthesizable into RTL by Xilinx Vivado HLS. For this tutorial we use one of the example models made available in the hls4ml repository.
If you use hls4ml on CentOS 7, please upgrade Python pip before moving
forward:
# CentOS 7 only
python -m pip install --user --upgrade pip
Clone the published hls4ml v0.2.0 release and install it:
git clone --recursive --branch v0.2.0 --single-branch \
  https://github.com/fastmachinelearning/hls4ml.git
cd hls4ml
python -m pip install .
Next we will convert a Keras model into a Vivado HLS accelerator. The conversion
uses the sample configuration from the pinned hls4ml release:
example-models/keras-config.yml. It points to a small three-layer multilayer
perceptron. The published release does not include the small input and expected
output set used by this ESP guide, so those two files are provided here:
Here are the steps to generate the Vivado HLS accelerator starting from the Keras model.
-
Move to the hls4ml root folder
-
Place
KERAS_3layer_input_features.datandKERAS_3layer_predictions.datinexample-models/keras -
Open
example-models/keras-config.ymland uncomment lines 3-4 (InputDataand OutputPredictions) -
cd example-models -
Convert the model:
hls4ml convert -c keras-config.yml. The result is the Vivado HLS project namedmy-hls-test. -
cd my-hls-test -
Run the C simulation of the Vivado HLS accelerator to test it and to produce the accelerator results in
tb_data/csim_results.log. Runvivado_hls -f build_prj.tcl "csim=1 synth=0 cosim=0 validation=0"
At this point the Vivado HLS accelerator generated by hls4ml is ready to be integrated in ESP, with the simple steps described in the next section.
Note: This demo has been tested on commit id:
4387457of the hls4ml repository.
2. Accelerator automatic integration
ESP provides an interactive script that generates all of the hardware and software sockets to quickly integrate a new hls4ml accelerator in a full SoC.
# Move to the ESP root folder
cd <esp>

# Run the accelerator initialization script and respond as follows
./tools/accgen/accgen.sh

=== Initializing ESP accelerator template ===

  * Enter accelerator name [dummy]: mlp3layers
  * Select design flow (Stratus HLS, Vivado HLS, hls4ml, Catapult HLS, RTL) [S]: h
  * Enter ESP path [<esp>]:
  * Enter the path of the project folder generated by hls4ml: <hls4ml-root>/example-models/my-hls-test
  * Enter unique accelerator id as three hex digits [04A]: 194
  * Configure PLM size and create skeleton for load and store:
    - Enter data bit-width (8, 16, 32, 64) [32]:
    - Enter the number of fixed point fractional bits [16]: 10
    - Enter input data size (number of words) [1024]: 16
      data_in_size_max = 16
    - Enter output data size (number of words) [32]: 5
      data_out_size_max = 6
    - Enter number of inputs that the hls4ml testbench has (tb_data/tb_input_features.dat) [1]: 8
      batching_factor_max = 8
  * Copying hls4ml project folder (<path to the my-hls-test project>) to accelerator directory
    (<esp-root>/accelerators/hls4ml/mlp3layers_hls4ml/hw). Renaming it 'hls4ml'.

=== Generated accelerator skeleton for mlp3layers ===
At this point the ESP accelerator is ready and is available to be instantiated
in an SoC.
The description of each parameter configured by the accelerator initialization script is reported below.
- Accelerator name: choose a unique name for the accelerator. Enter mlp3layers.
- Design flow: choose the target HLS tool. Enter h to select hls4ml.
- ESP path: if you run the script from the ESP root folder, leave blank to confirm. Otherwise, enter the path to ESP.
- hls4ml-generate project path: insert the path of the
my-hls-testproject generated by hls4ml according to the instructions of section 1 of this tutorial (for example,<hls4ml-root>/example-models/my-hls-test). - Accelerator ID: enter a unique device ID for the accelerator in the range 0x040-0x3FF. This is a three-digit hexadecimal number. Note that if any two accelerators have the same ID, the SoC generation step will fail. Enter 194.
- Data bitwidth: select the size of the data word for the accelerator. This
can be one byte (8), half word (16), word (32), or double word (64). Look at
the definition of
model_default_tinmy-hls-test/firmware/parameters.h. The first parameter passed toap_fixedis the minimum data bitwidth for this accelerator. Even though 16 bits is enough, for this tutorial we enter 32. - Fixed-point fractional bits: insert the number of fractional bits of the
fixed point data type used by the hls4ml accelerator. Look again at the
definition of
model_default_tinmy-hls-test/firmware/parameters.h. The second parameter passed toap_fixedis the number of fixed-point fraction bits for this accelerator. Enter 10. - Input data size: specify the size of the input data token. This is the
unit of data that your kernel of computation processes per invocation. Use
the value of
N_INPUT_1_1inmy-hls-test/firmware/parameters.h. Enter 16. - Output data size: specify the size of the output data token. This is the
unit of data that your kernel of computation outputs per invocation. Use
the value of
N_LAYER_<last-layer>inmy-hls-test/firmware/parameters.h. Enter 5. - Number of inputs: specify the number of iterations of the computation kernel to be executed at each invocation of the accelerator. Enter number of inputs that the hls4ml testbench takes (aka the number of lines of tb_data/tb_input_features.dat). Enter 8. >
Executing the initialization script with the above parameters,
generates the accelerator source files and testbench in SystemC,
together with the HLS scripts and the information for the private
memory generator. These files are located at the path
accelerators/hls4ml/mlp3layers_hls4ml/hw.
In addition, the accelerator’s device driver, bare metal application
and user-space linux application are generated at the path
accelerators/hls4ml/mlp3layers_hls4ml/sw.
# Complete list of files generated and modified
<esp>/accelerators/hls4ml/mlp3layers_hls4ml
├── hw
│   ├── mlp3layers.xml       # Accelerator description and register list
│   ├── hls                  # HLS scripts
│   │   ├── common.tcl
│   │   ├── custom.tcl       # Customizable system-level configuration
│   │   ├── directives.tcl   # User-defined HLS directives
│   │   └── Makefile
│   └── hls4ml               # Project folder generate by hls4ml
│   ├── inc                  # Folder for code header files
│   │   ├── espacc_config.h  # Data types and local memory size definitions
│   │   └── espacc.h         # Constants and defines for the ESP accelerator
│   ├── src                  # Accelerator source files
│   │   └── espacc.cc        # Accelerator specification
│   └── tb
│       └── tb.cc            # Testbench
└── sw
    ├── baremetal            # Bare-metal test application
    │   ├── mlp3layers.c
    │   └── Makefile
    └── linux
        ├── app              # Linux test application
        │   ├── mlp3layers.c
        │   └── Makefile
        ├── driver           # Linux device driver
        │   ├── mlp3layers_hls4ml.c
        │   ├── Kbuild
        │   └── Makefile
        └── include
            └── mlp3layers_hls4ml.h
3. SoC design and testing
HLS build
After generating mlp3layers_hls4ml, run HLS from the SoC working folder for
the FPGA board you want to target. The example below uses the Xilinx VCU118
board:
# Move to the Xilinx VCU118 working folder
cd <esp>/socs/xilinx-vcu118-xcvu9p

# Run behavioral simulation and HLS for the hls4ml accelerator
make mlp3layers_hls4ml-hls
This target creates the HLS work directory, runs Vivado HLS for the available
implementations, and installs the generated RTL into the technology library used
by the SoC flow.
SoC configuration
Configure the SoC with the ESP configuration GUI:
make esp-xconfig
Follow the “Debug link configuration” instructions from the “How to: design a
single-core SoC” guide. Select the CPU
architecture you want to use, choose a layout with one memory tile, one
processor tile, one I/O tile and one MLP3LAYERS_HLS4ML accelerator tile, then
save with Generate SoC config.
RTL simulation
Run a full-system RTL simulation of the accelerator driven by the bare-metal application:
# Compile bare-metal application
make mlp3layers_hls4ml-baremetal

# Modelsim
TEST_PROGRAM=./soft-build/<cpu>/baremetal/mlp3layers_hls4ml.exe make sim[-gui]

# Xcelium
TEST_PROGRAM=./soft-build/<cpu>/baremetal/mlp3layers_hls4ml.exe make xmsim[-gui]
Replace <cpu> with the processor selected in the ESP GUI, for example
ariane, leon3 or ibex.
FPGA prototyping
Follow the “FPGA prototyping” instructions from the “How to: design a single-core SoC” guide. As in the RTL simulation step, specify the generated bare-metal executable when launching a bare-metal run:
TEST_PROGRAM=./soft-build/<cpu>/baremetal/mlp3layers_hls4ml.exe make fpga-run
For Linux, compile the accelerator driver and user application, rebuild the
Linux image, boot it on FPGA, and run the test application:
make mlp3layers_hls4ml-driver
make mlp3layers_hls4ml-app
make linux
make fpga-run-linux
$ cd /applications/test/
$ ./mlp3layers_hls4ml.exe
FPGA prototyping with prebuilt material
With the provided prebuilt material, you can run the tutorial on FPGA directly. Each packet is marked with the first digits of the Git revision it was created and tested with.
The packet contains the following:
- The source code, testbench and HLS scripts for the mlp3layers
accelerator (
accelerators/hls4ml/mlp3layers_hls4ml) - The bare-metal test application and the Linux device driver and
test application for the mlp3layers accelerator
(
soft/[ariane|leon3]/drivers/mlp3layers) - Two working folders for Xilinx VCU118, each including:
- The Linux image (
linux.bin) - The bare-metal application (
mlp3layers.bin) - The boot loader image (
prom.bin) - The FPGA bitstream (
top.bit) - The hidden configuration files for the design (
.grlib_configand.esp_config) - A script to run the design on FPGA (
runme.sh)
- The Linux image (
Decompress the content of the packet from the ESP root folder to make sure all files are extracted to the right location.
cd <esp>
tar xf ESP_hls4ml_GitRev.efd6c9c.tar.gz
Enter one of the SoC instances extracted from the packet.
cd socs/hls4ml_acc_vcu118
Follow the “UART interface” instructions from the “How to: design a
single-core SoC” guide,
then launch the runme.sh script
# Execute the bare-metal test
./runme.sh mlp3layers
# Boot Linux
./runme.sh
Finally From the ESP Linux terminal run the mlp3layers test application
$ cd /applications/test/
$ ./mlp3layers.exe